big-data.
Streams in. Watchlist out.
A real-time movie recommender: Kafka streams the dataset into a lakehouse on MinIO, Spark builds the similarity model, and a Flask web app serves similar-title picks while a Streamlit dashboard monitors the stream live. Team project (5) for the Big Data & Data Lakehouse course.
JSON + Parquet
raw and lakehouse formats
7
pipeline stages · producer → dashboard
5 min
model rebuild loop
5
engineers on the team
Demo · exported output
Ask for a movie, get its neighbours.
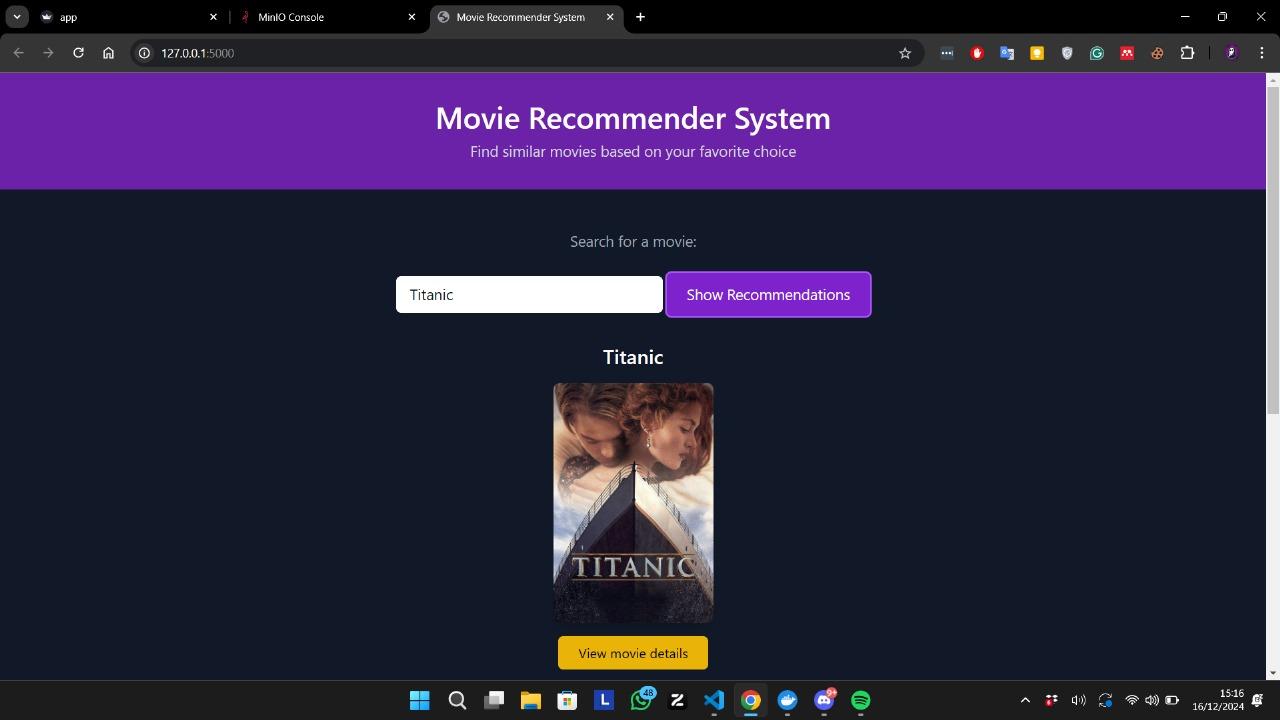
Pick a title and see the five nearest neighbours the similarity model returns, exported from the served app.
Try a title
Nearest neighbours
Toy Story
- 01Toy Story 20.493
- 02Toy Story 30.455
- 03The 40 Year Old Virgin0.346
- 04Toy Story 40.333
- 05While You Were Sleeping0.315
Cosine similarity over the CountVectorizer features built from overview and genre.
Recomputed with the same CountVectorizer plus cosine step the Spark job runs, over the project's 10,000-title dataset.
Pipeline Workflow
Kafka Streaming
MinIO Lakehouse
Spark Model Build
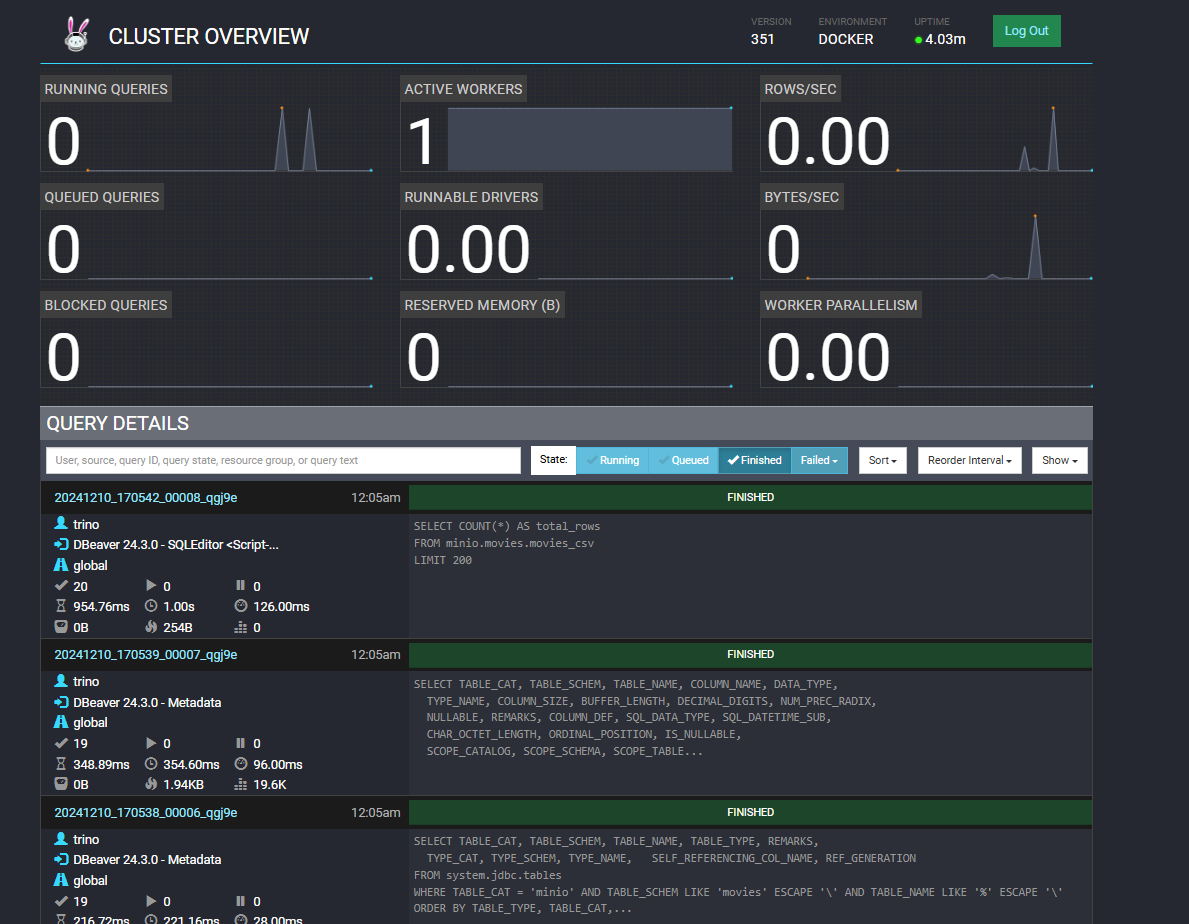
Trino Query Layer
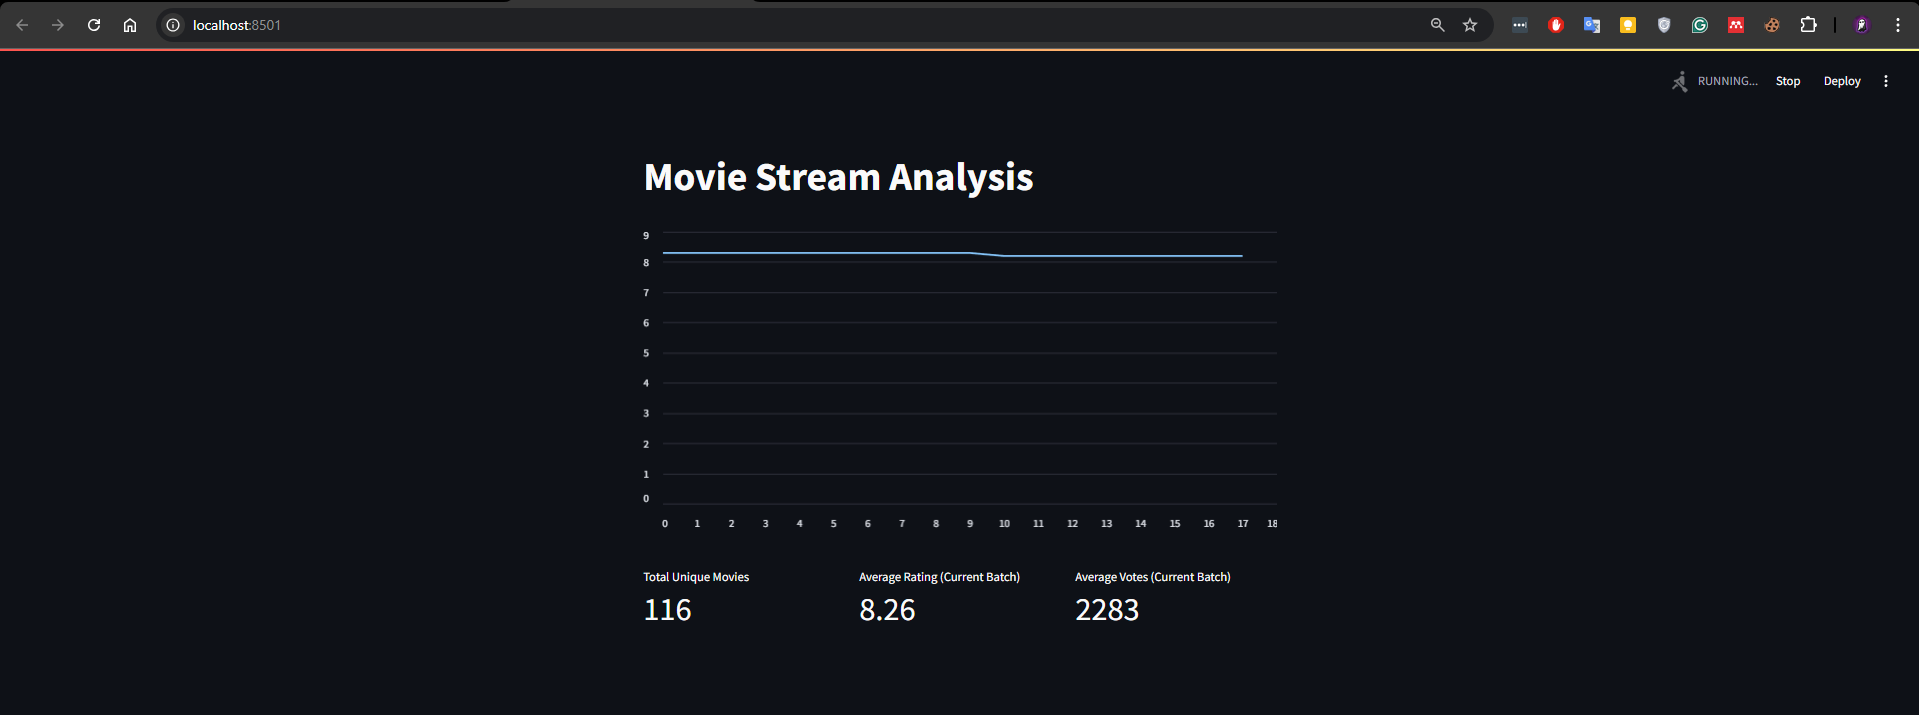
Live Stream Monitor
Recommendation UI
Tech Stack
The brief · problem → approach → result
01 / The problem
Recommendations built on a static CSV stop being useful the moment data moves. The brief: a recommender that ingests streams, stores them properly, and serves queries — the whole data stack, not just a model.
02 / The approach
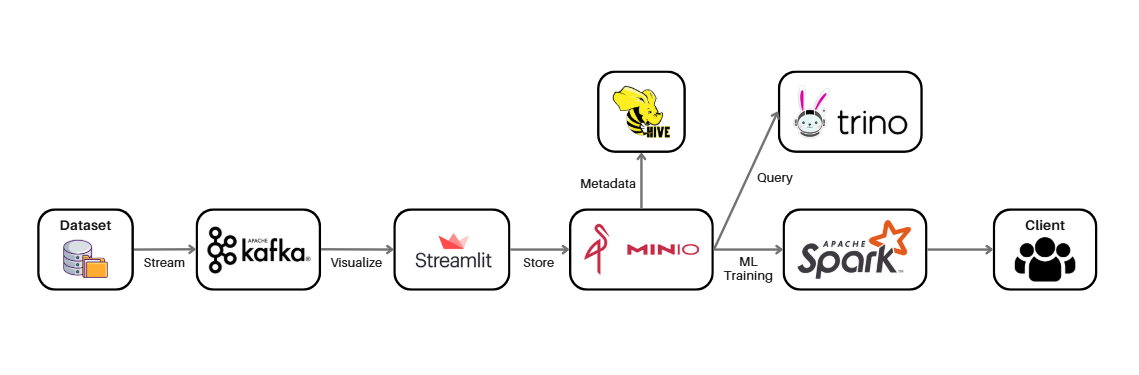
Kafka streams the dataset into a MinIO lakehouse; Spark rebuilds a CountVectorizer + cosine-similarity model on a 5-minute loop; Trino sits on top as the SQL layer. Flask serves the recommender UI and Streamlit monitors the stream live.
03 / The result
An end-to-end recommender where one script (automation.py) keeps the whole lakehouse alive — every service wired by a single Docker Compose, built by a team of 5.
The Pipeline
Producer
replays the dataset
Kafka
movies topic broker
MinIO
batched lakehouse
Spark
similarity model
Trino
sql query layer
Web UI
similar-title picks
Monitor
live stream dashboard
Every piece is containerized. The producer replays the movie dataset into a Kafka topic, the Streamlit dashboard consumes it live and batches rows to MinIO every two minutes, and a Spark job rebuilds the recommendation model on a schedule. Trino sits on top as the SQL query layer.
Core Features
Streaming Ingestion
A producer replays the movie dataset into the movies topic with duplicate prevention, while the Streamlit dashboard consumes the stream live: total movies streamed, average rating, average votes, and a rolling line chart.
Lakehouse & Processing
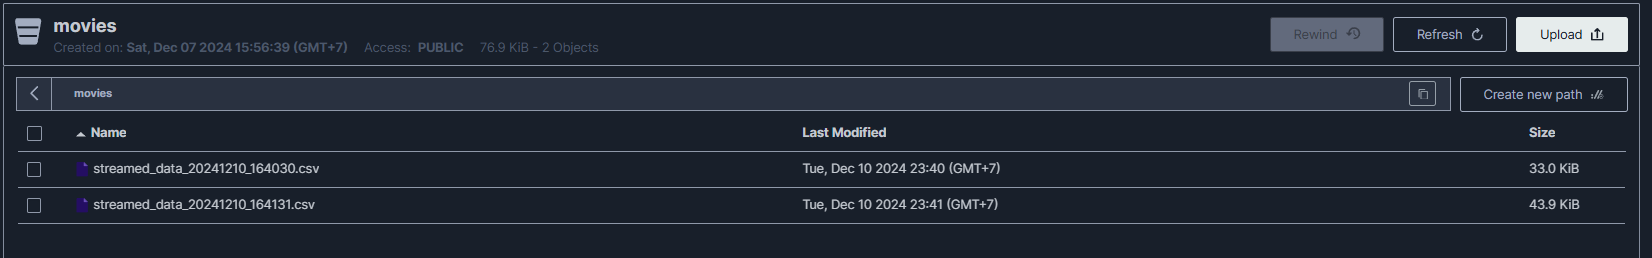
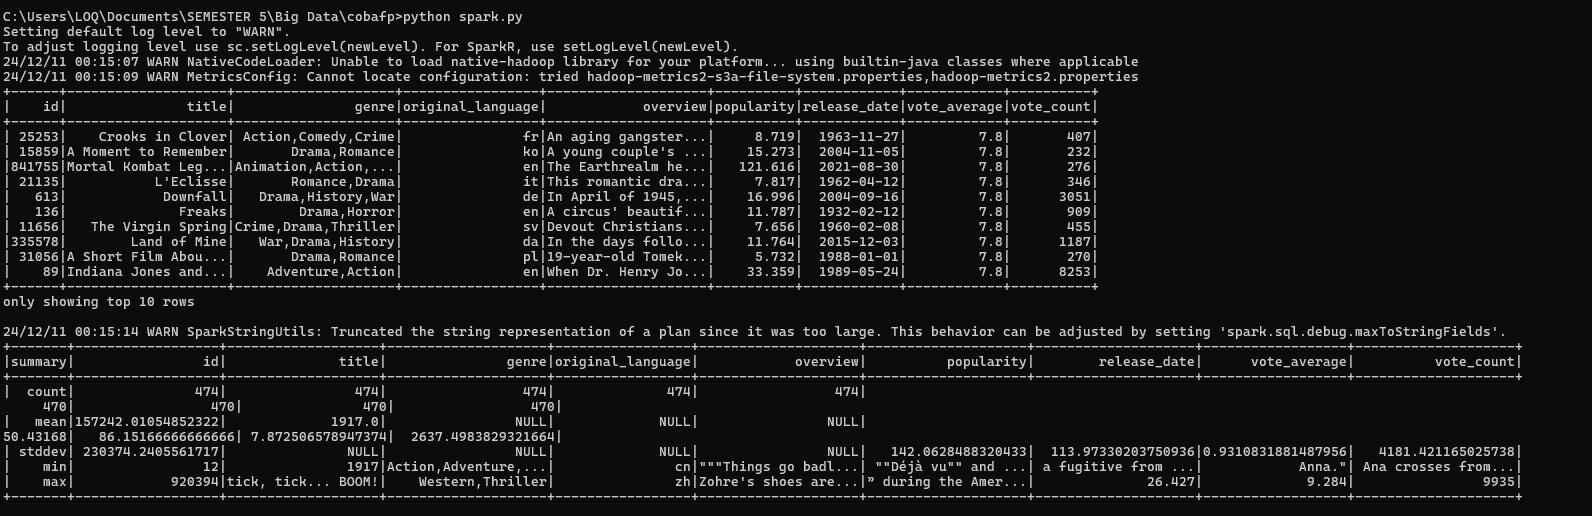
MinIO plays the object storage layer. Buffered rows are batched out as CSV, and the Spark job reads them back (s3a://movies/*.csv), tokenizes overviews, runs CountVectorizer, and computes a cosine similarity matrix exported as .pkl model files.
Query & Dashboard
A Flask web app serves the recommender: search a title, get the ten most similar movies with posters and ratings, and jump straight to IMDb. Trino, Hive Metastore, and MariaDB form the SQL layer over the lake, explored from DBeaver.
Automation
4 threads in automation.py
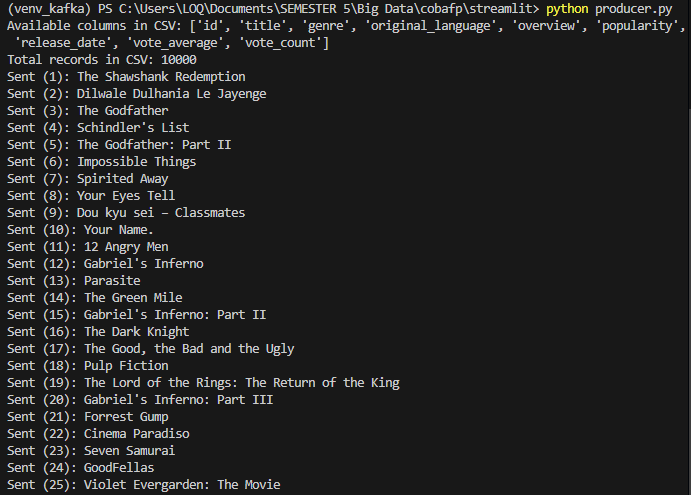
- 01Producer. Replays dataset.csv into the movies topic, one record every half second, skipping duplicates.
- 02Dashboard. Boots the Streamlit monitor that visualizes the stream live and flushes batches to MinIO.
- 03Scheduler. Reruns the Spark job every five minutes to rebuild the similarity model from the lake.
- 04Monitor. Watches for new .pkl model files and restarts the Flask recommender when a fresh model lands.
Wired by Docker Compose
Kafka + Zookeeper
Broker and coordinator for the movies topic.
MinIO
Object storage for raw batches, mounted from ./data.
Trino + Hive Metastore
SQL query layer with a MariaDB-backed metastore.
Streamlit
Live stream monitor served on port 8501.
Design principle: one script runs the whole stack. Producer, dashboard, model training, and hot-swap monitoring all live in automation.py, so a single command keeps the lakehouse alive.
Technology Architecture
fp-big-data/
├── streamlit/                  # live stream monitor
│   ├── app.py                  # kafka consumer: metrics, chart, minio batching
│   ├── producer.py             # replays dataset.csv into the movies topic
│   ├── dataset.csv             # movie dataset
│   └── Dockerfile
├── frontend/
│   └── index.html              # flask recommendation ui
├── app.py                      # flask api: similarity search + tmdb posters
├── spark.py                    # countvectorizer + cosine similarity model
├── automation.py               # producer, dashboard, spark loop, model monitor
├── conf/
│   └── metastore-site.xml      # hive metastore config
├── etc/                        # trino server config
├── data/                       # minio storage volume
└── docker-compose.yml          # kafka, minio, trino, streamlit, metastore