boothme.
Strike a pose. The AI does the rest.
A web-based AI photo booth: snap a selfie, and Stable Diffusion 1.5 (revAnimated) turns you into an illustrated character. Pick a frame, build a collage, download the strip. Team project (3) with real-time face tracking on MediaPipe.
1.5
stable diffusion · revAnimated
4
hops · capture → generate → frame → download
3
engineers on the team
0
installs — runs in the browser
Demo · recorded run
Snap, then transform.
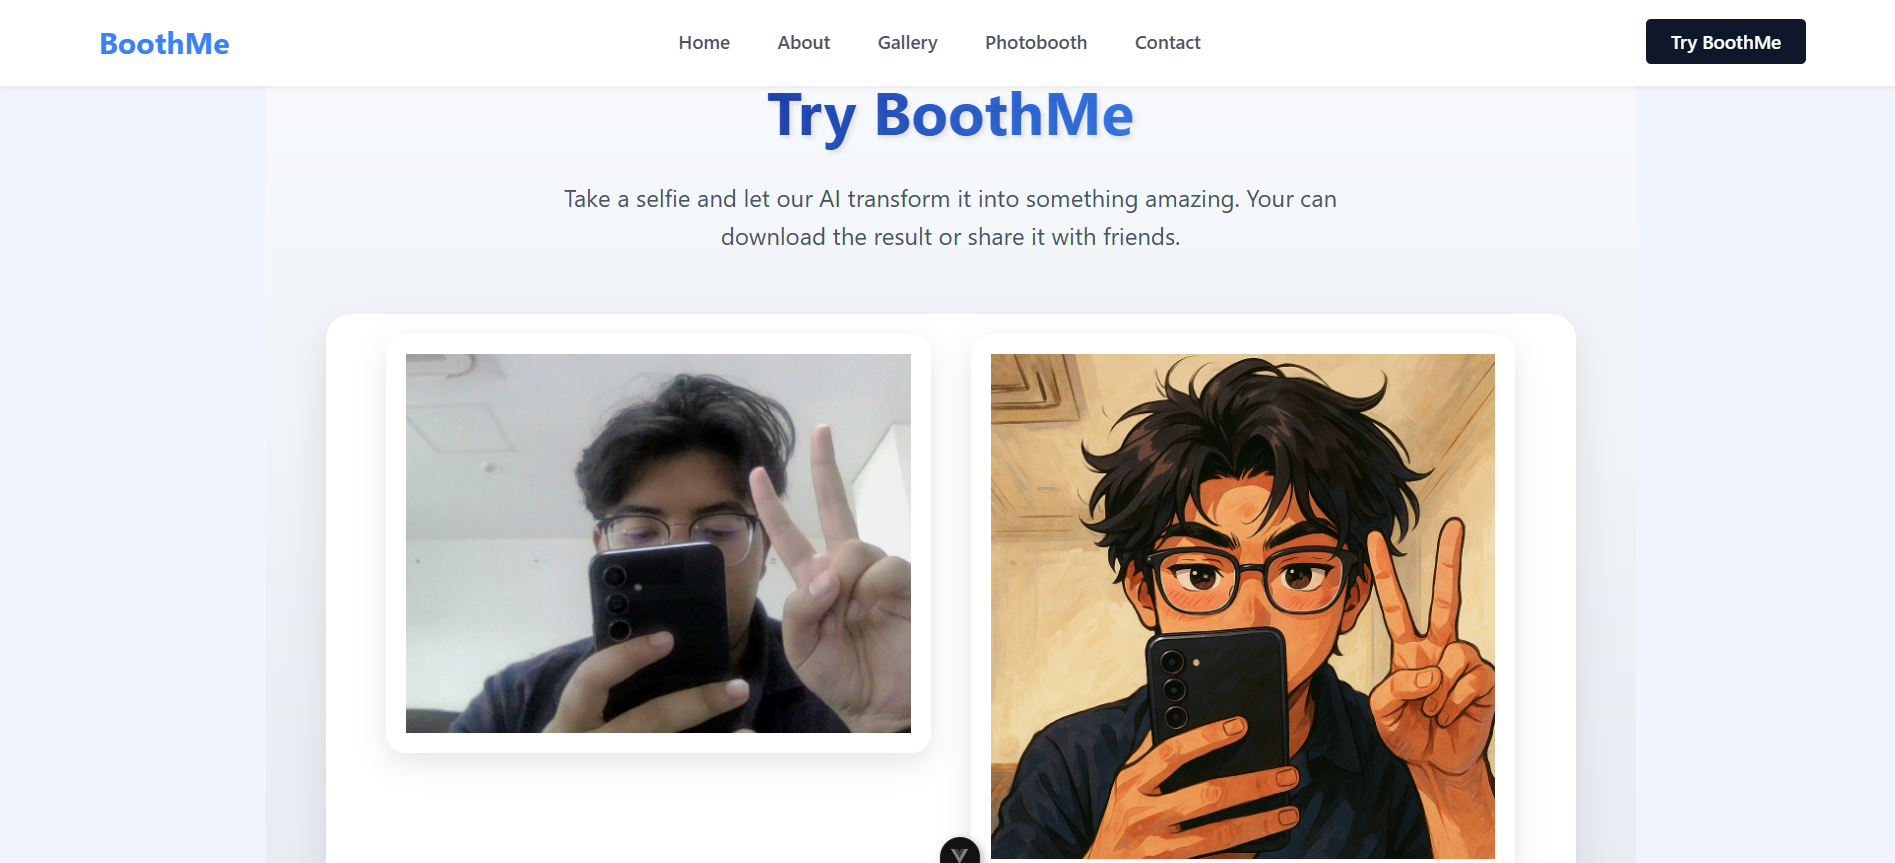
A real selfie and the frame Stable Diffusion returned, from the same session. Recorded on a local GPU, so the model is not served publicly.
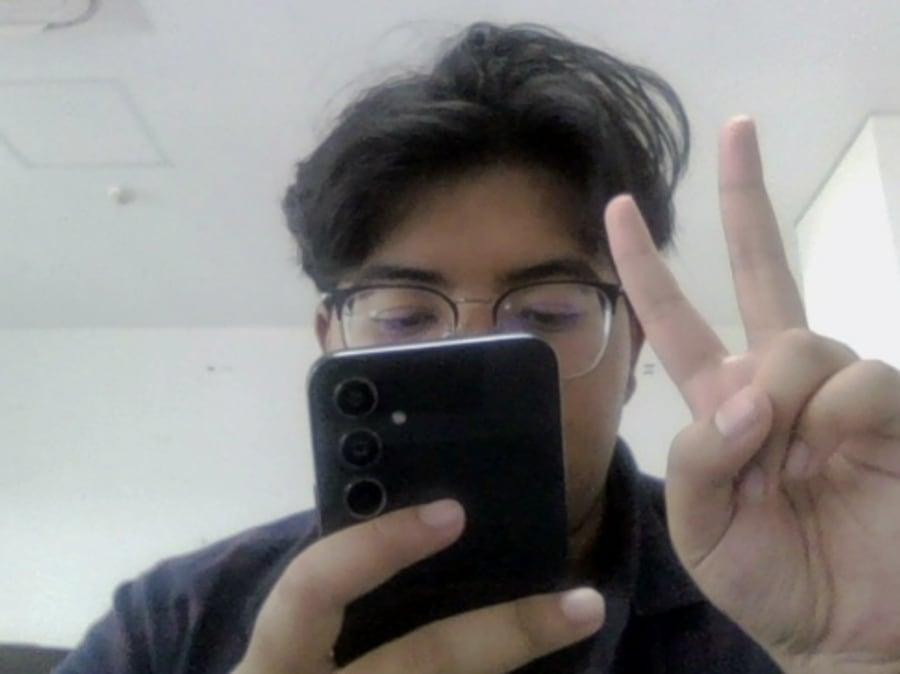
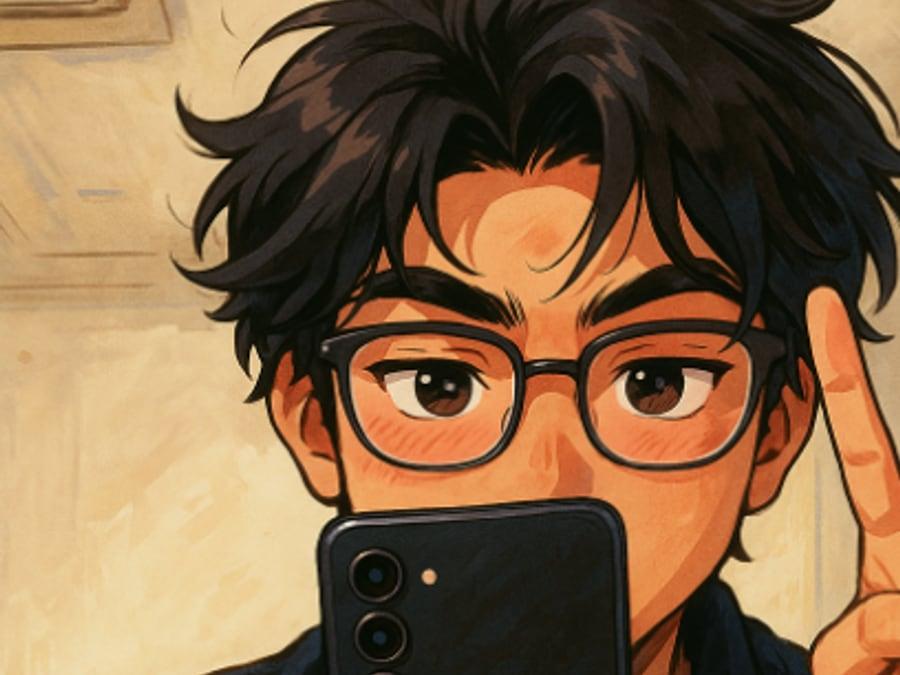 AI frame
Same session · Stable Diffusion 1.5 revAnimated
Same session, same frame. The illustrated panel is cropped to match the selfie for the comparison.
Before & After
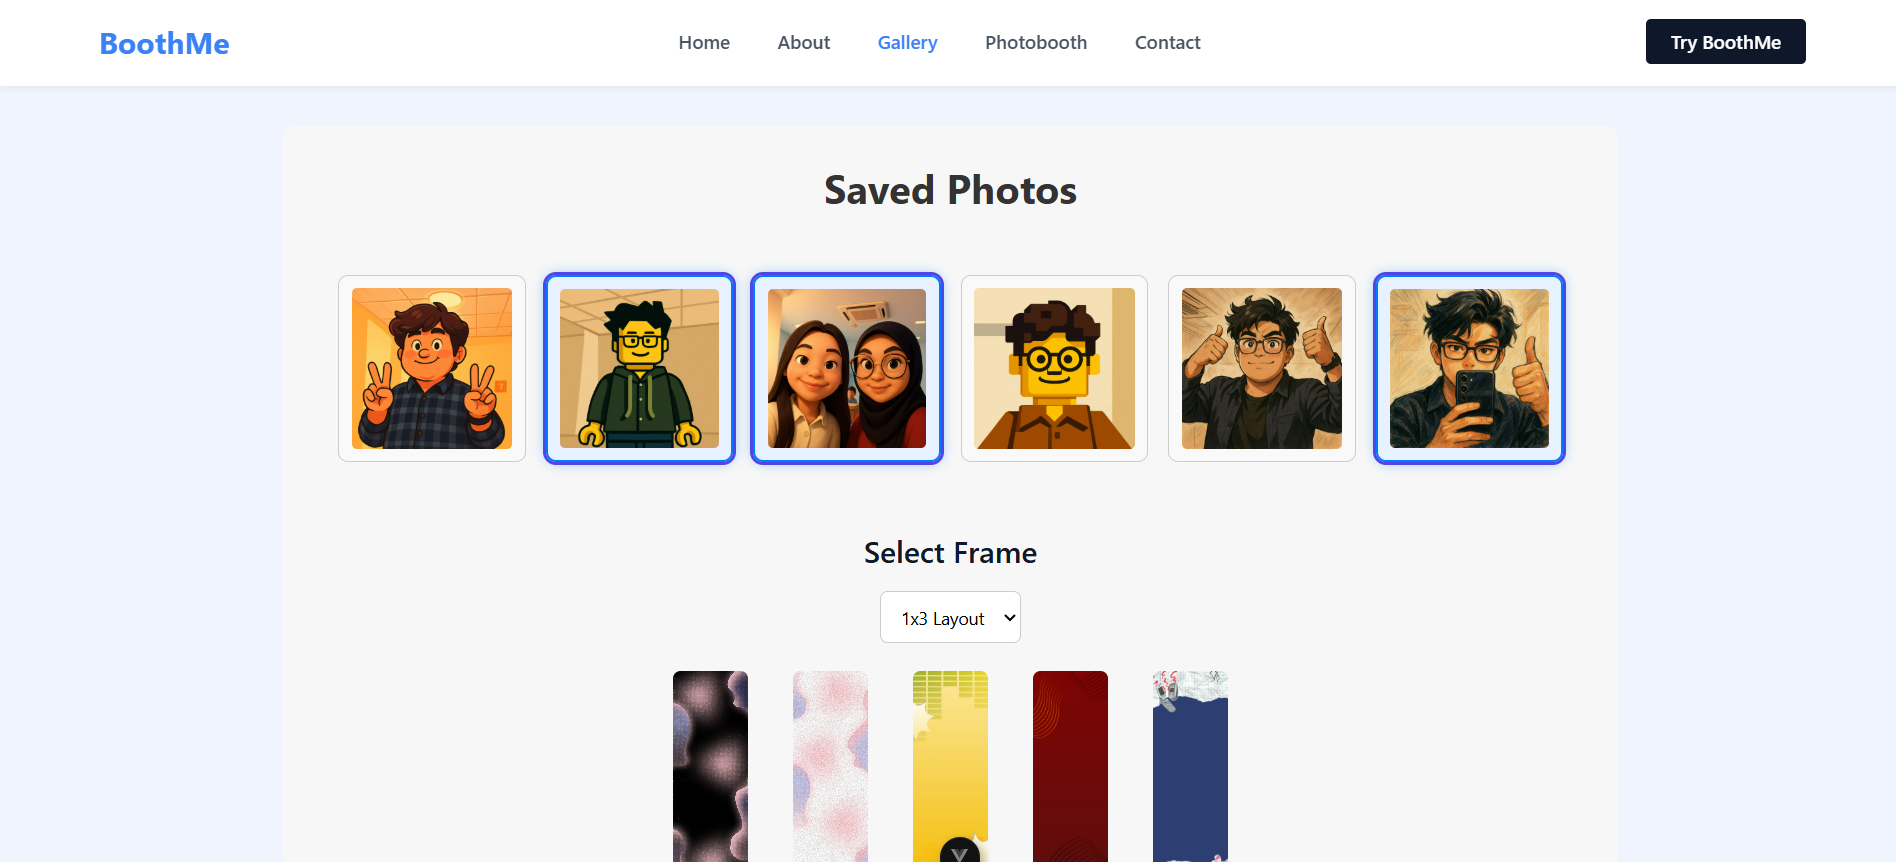
Saved Photos & Frames
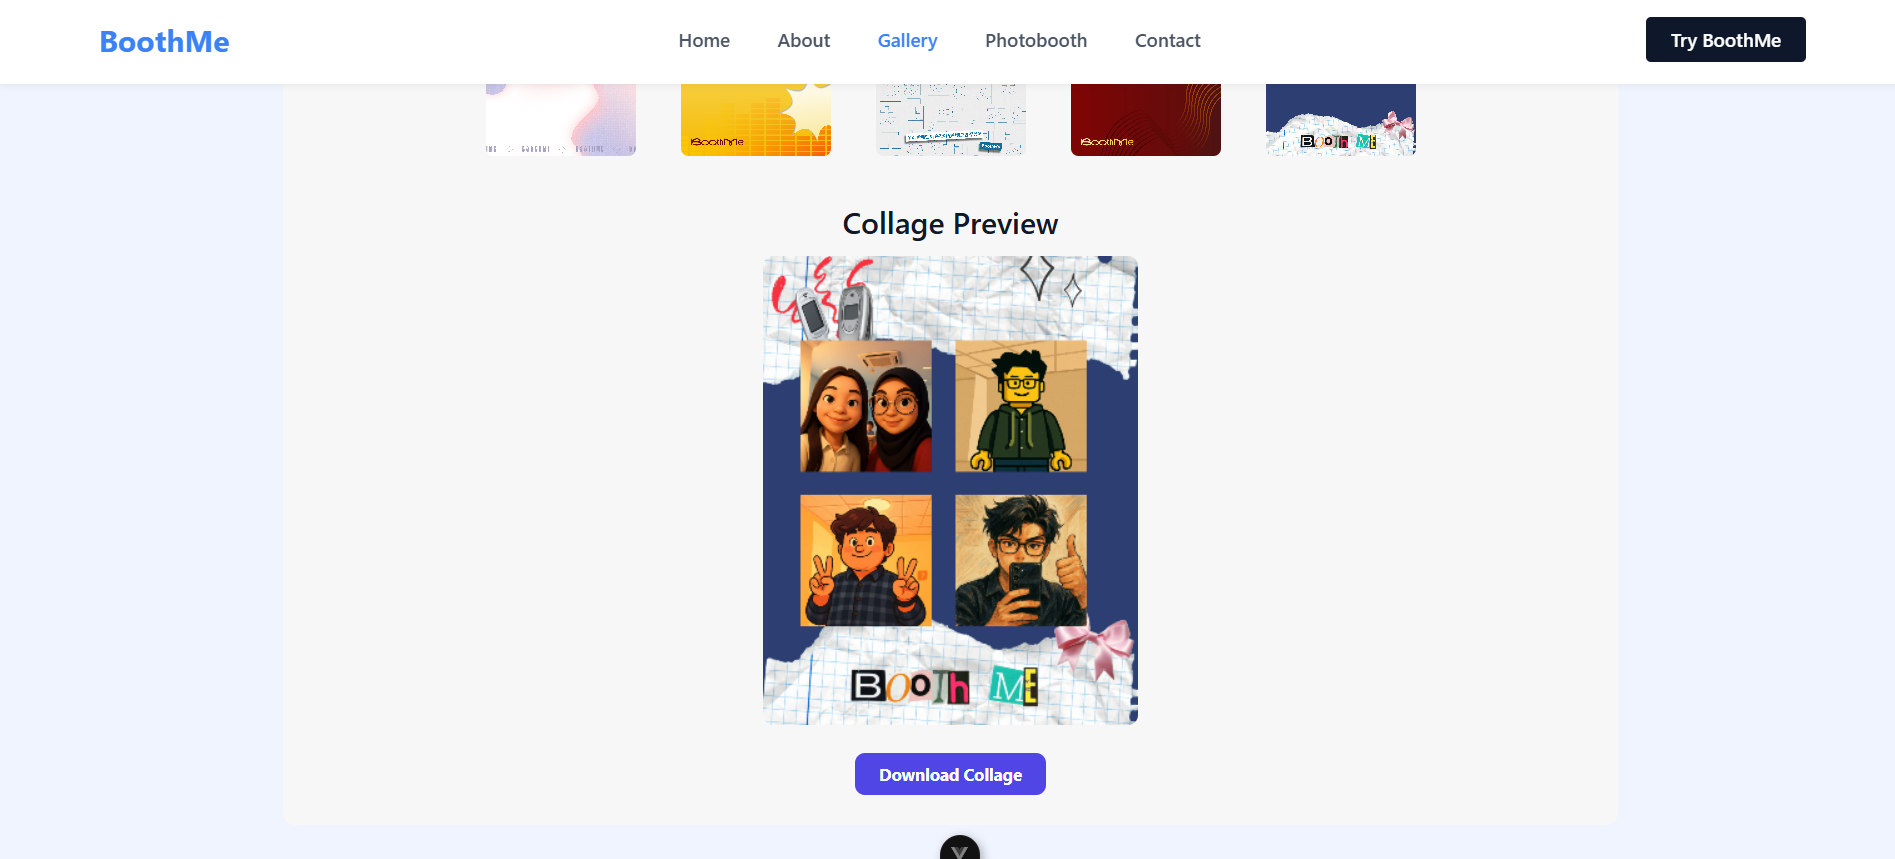
Collage Preview
Tech Stack
The brief · problem → approach → result
01 / The problem
Photo booths are stuck on the same preset filters. We wanted the booth to repaint you into a new world instead.
02 / The approach
MediaPipe tracks the face in the browser; the frame streams base64 to an Express API that proxies the Stable Diffusion WebUI on GPU; Vue 3 drives the booth, frames, and collage.
03 / The result
A browser-based AI photo booth — capture, generate, frame, download — fully containerized, built by a team of 3.
The Booth Flow
Capture
webcam + face tracking
Generate
sd 1.5 revAnimated
Frame
pick photos + layout
Download
collage strip
No install needed: the experience runs in the browser, face tracking frames the shot, and the illustration is generated on a GPU behind the API before landing on a themed collage you can download or share.
Core Features
Face-Aware Camera
A live webcam view with real-time face detection via Google MediaPipe, so the framing follows you before the shutter even clicks.
Style Engine
Captured frames stream to a Node.js (Express) API as base64, get proxied to the Stable Diffusion WebUI, and come back as illustrated portraits generated by the revAnimated model.
Frame Studio
Saved photos live in a gallery where you can multi-select shots, pick a layout like 1x3, preview the collage on a themed frame, and download the final strip.
Under the Hood
4 hops from selfie to illustration
- 01Capture. The Vue 3 client grabs a webcam frame and tracks the face with Google MediaPipe.
- 02Encode. The frame is packed as a base64 image stream and POSTed to the Express server.
- 03Generate. Express proxies the payload to the Stable Diffusion WebUI API running on the GPU.
- 04Return. The illustrated result comes back to the client, ready for frames and collage.
Built to run heavy
GPU
NVIDIA + CUDA
Stable Diffusion inference needs a CUDA-capable NVIDIA GPU.
MEMORY
8GB+ RAM
Enough headroom to keep the containers and model responsive.
STORAGE
10GB+ free
Disk space for the model weights and Docker images.
Design principle: the browser stays light. Face tracking and frame picking run in the client, while all heavy generation happens on the GPU behind a single API hop.
Technology Architecture
boothme/
├── fe/                         # vue 3 (vite) client
│   ├── src/                    # views: home, gallery, photobooth, try, about
│   ├── e2e/                    # playwright end-to-end tests
│   └── Dockerfile
├── backend/                    # node.js express api
│   └── index.js                # proxies image streams to sd webui
├── src/                        # express + socket.io service (sessions & photos)
│   ├── models/
│   └── routes/
├── stable-diffusion/           # sd webui container
│   └── Dockerfile
└── docker-compose.yml          # fe, backend, sd webui services